01
Workflow & Document Automation
Automate repetitive paperwork, schema validation, and multi-system reconciliation without fragile copy-paste errors.
We build reliable automations and secure data pipelines for teams that need clean code, full IP ownership, and predictable cloud costs.
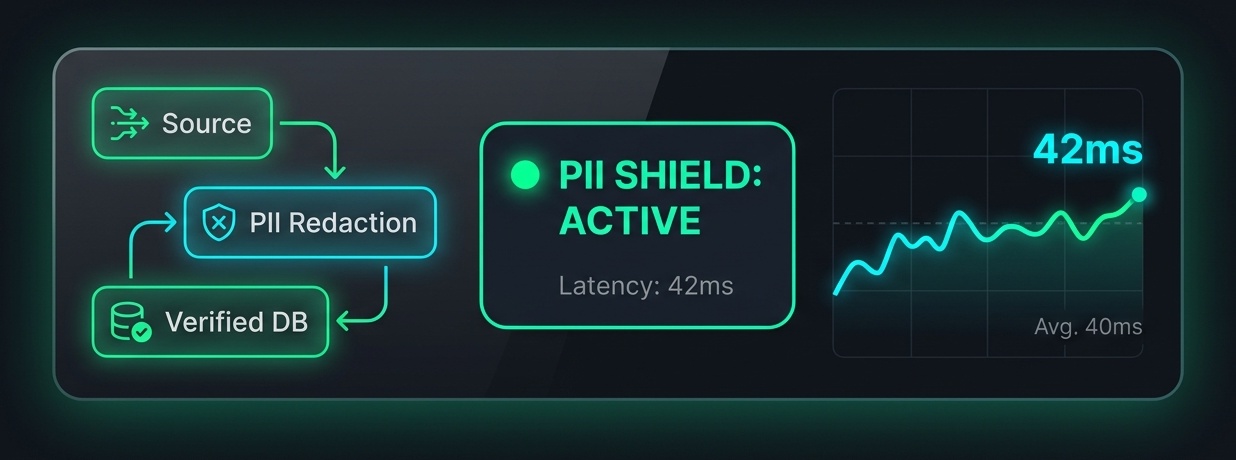
Customer data exposed
Installed local redaction gateway to scrub personal info before transit.
3 hrs/day manual invoice matching
Built automated document auditor that cross-references and reconciles paperwork 24/7.
Data trapped across 4 tools
Consolidated fragmented records into a single, clean database.
Most internal automations break down between initial testing and daily operations. Unmonitored scripts fail quietly, cloud bills jump unexpectedly, and customer data gets exposed. We build dependable pipelines that stay stable under real workloads.
Webhooks break without warning. You only find out after a customer complains or an order stalls.
An unmonitored loop runs overnight, quietly eating through budget credits before anyone notices.
Customer info, order records, or proprietary notes get sent directly to third-party endpoints without masking.
Your core business logic is trapped in proprietary SaaS tools with mounting monthly licence fees.
Every single step is logged. When a malformed document comes in, you can pinpoint the exact cause and step that failed.
Smart caching and hard budget ceilings cut compute waste and stop runaway spend automatically.
Personal details and financial figures are scrubbed inside your own network before anything leaves your servers.
All software is deployed to your own GitHub repo. Zero recurring licences, no black boxes, no lock-in.
Automate repetitive paperwork, schema validation, and multi-system reconciliation without fragile copy-paste errors.
Audit execution paths at every node in real time. Programmatic budget kill-switches and human approval gates keep operations reliable.
Deploy pipelines directly inside your private cloud network. Sensitive customer records are sanitised before payloads leave your servers.
Clean Git repositories, zero vendor lock-in, and enterprise infrastructure running inside your own cloud. Engineered with LangGraph, OpenTelemetry, Docker, and isolated VPC perimeters.
Direct access to senior engineers—no sales reps or account managers. We map your current friction, build a working pilot, harden it for production, and hand you the keys.
Map bottlenecks, APIs, and security boundaries across existing workflows.
Build and benchmark an isolated working prototype on real company data.
Deploy to private VPC with telemetry, automated circuit breakers, and rate limits.
Complete code ownership, comprehensive runbooks, and zero recurring software licences.
Map current bottlenecks, security boundaries, and high-ROI workflows.
Build and benchmark a working isolated prototype on actual company data.
Deploy to your private VPC with telemetry, automated circuit breakers, and rate limits.
Complete code ownership, comprehensive runbooks, and zero recurring software licences.
We build and maintain working reference implementations across observability, data privacy, automated reconciliation, and enterprise search. When you evaluate us, we walk your engineering team directly through the live architecture.
Operational dashboard engineered to trace multi-step background processes, monitor API response times, and manage cloud spend in real time.
Inline proxy service designed to sanitize customer records and confidential company numbers before payloads leave your private network.
Automated matching pipeline that parses, cross-references, and reconciles unstructured paperwork across separate tools.
Enterprise search pipeline that turns scattered internal documents, PDFs, and wiki pages into fast, accurate answers.
You do, completely. No recurring licences or proprietary platform lock-in. All code and documentation live in your own GitHub repository.
No-code tools fail silently, get expensive quickly as volume grows, and lock your core logic in their systems. We write modular, standard code with clear error logs you can actually debug.
No. Messy data is normal. We build data cleaning and schema validation directly into the ingestion pipelines so malformed records get caught automatically.
30 minutes · No sales pitch · Direct engineer consult